Search for Ways to Improve Response Times for Support Tickets by Deleting the Queue
Search for ways to improve response times for support tickets? The fastest path is removing queued tickets entirely, not staffing the queue harder.
Every search for ways to improve response times for support tickets eventually runs into the same uncomfortable arithmetic: response time is a function of how much queued work exists, not of how fast your agents move through it. Shaving two minutes off each reply at 600 tickets a month buys you about 20 hours. Deleting a third of those tickets buys the same 20 hours permanently, without asking anyone to work harder.
Most support advice answers the wrong question. It asks how to make the queue move faster. The better question is which tickets should never have entered the queue.
The Short Version: Delete Queued Work Before You Speed It Up
If your first response time is measured in hours and the pile keeps growing, your problem is queue composition, not agent velocity. Every ticket carries a fixed cost you cannot optimize away: the context switch, the lookup, the typing, the closing note. Cutting that cost per ticket helps at the margin. Removing the ticket removes the whole cost.
"A 600-case November costs a seasonal temp about $2,240 in wages plus two weeks of training before they are productive." That line is not decoration. Replacing queued work with capacity you have to hire and train is the slowest and most expensive of your options, and it is the one most teams reach for first.
What Ticket Response Time Really Measures
The industry default describes it as the elapsed time between a customer's message and the first human reply, and that definition quietly builds in the assumption that a human must be involved before the clock stops. That assumption is where most response-time initiatives quietly stall. Someone sets an SLA target, then everybody optimizes the route to a human.
Measuring that way hides the more revealing number: how many tickets in the queue actually needed a person at all. A "where is my order?" message, a refund status check, a delivery address change, all have factual answers sitting in your order system. They wait in the queue because your process routes everything to the same place, not because they are difficult.
The concept differs from adjacent ones you may already track. Resolution time measures how long a case stays open after it becomes a case. Response time measures how long it sits before anyone touches it. Abandonment rate measures how many customers give up before either happens. Only the first two are affected by ticket composition, which is why queues that grow with sales break response time first and loudest.
How It Works Under the Hood
A helpdesk is three components: an intake that creates a ticket, a routing layer that assigns it, and a resolution step that closes it. Response time is the gap between intake and the start of resolution. Shrink the gap structurally and the metric moves without anyone typing faster.
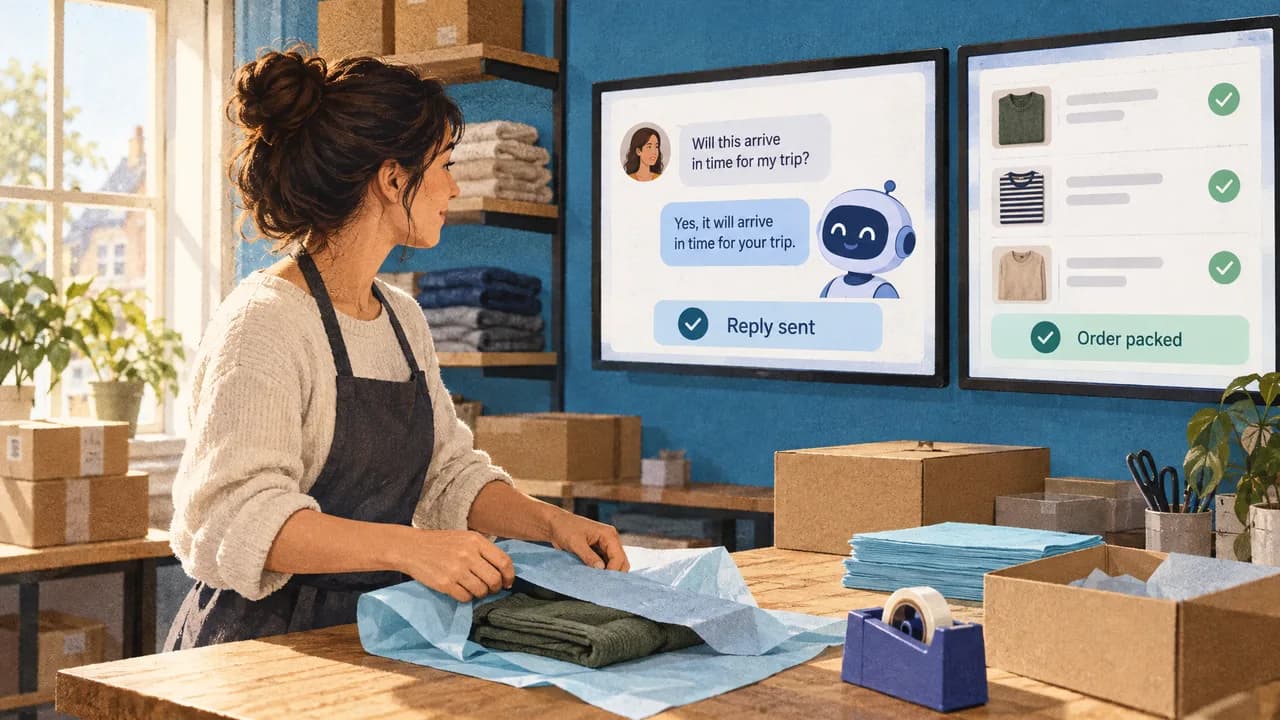
The mechanical version of that is a teammate that logs into the helpdesk you already use as an ordinary user account, reads the case, pulls the answer from approved policy and order data, and posts a reply as a readable, overrideable ticket. No migration, no new platform, no parallel inbox for your agents to forget about, because the work happens where the work already lives. When the case falls outside the defined scope, it transfers to a human teammate with the context attached.
Our own teammates run with restricted case scope and read-only, least-privilege tools. That constraint is the point rather than a workaround. A system that can only read order records cannot issue a refund it should not have issued, which is why we can hand it order status, refund checks, and delivery changes and still sleep. If you want the cost side of that arithmetic worked through, we published a breakdown of what AI support actually costs per ticket per ticket against the human alternatives.
Why this does not work on every ticket type
Order status, return and refund questions, delivery changes, order edits, and discount codes have factual answers and short decision trees. Angry customers, damaged-goods disputes, and unusual return requests have neither. A first reply from a machine reads as dismissal, not speed. Those cases should escalate to a person within the same minute they arrive.
The Step-by-Step Approach
The order matters here, because each step's output feeds the next one.
- Export 30 days of tickets and label each one by whether it needed a judgment call or a data lookup. You cannot choose a fix until you know the split.
- Rank the lookup tickets by volume, not by how annoying they are. The top three categories usually account for most of the repeating work.
- For each of those categories, ask whether the answer lives in a place you would trust a new hire to read from. If yes, the category is automatable. If the answer requires a policy interpretation, it is not.
- Write down the escalation rule before you automate anything: what happens when the customer's question is out of scope, when the data is contradictory, or when the tone turns hostile.
- Turn on one category, measure first-response time and satisfaction on that category alone for 30 days, then add the next one.
Step four is the one teams skip. It is also the step that decides whether automation improves your response time or merely relocates the wait to a place nobody is measuring.
What to Look For
The dimensions that separate a workable approach from a demo are mostly about limits, not features. Anyone can show a reply being generated. The question is what happens on the ticket that breaks the pattern.
| Dimension | What to look for |
|---|---|
| Escalation path | A defined, fast route to a human when the case leaves the approved scope |
| Data access | Read-only, least-privilege tools rather than broad write permissions |
| Where it lives | Inside your current helpdesk as a normal user, not a separate dashboard |
| Accountability | A named owner who audits traffic and reports on it, not a self-serve tool you maintain alone |
| Volume ceiling | An honest stated maximum, so you know whether your volume fits |
| Setup burden | Whether the vendor trains and runs it, or hands you a configuration screen |
The trade-off running through all six is control against upkeep. Broad permissions and full autonomy produce more automated closes, and more ways to get it wrong on a case that mattered. Restricted scope costs you some coverage and buys you predictability.
If your problem is specifically that volume keeps rising while margin does not, the tactics in handling more support tickets without breaking margin pair well with this evaluation. Read that one if your bottleneck is cost rather than speed; read this one if the queue itself is the problem.
Common Mistakes to Avoid
Buying the tool before labeling the tickets is the mistake that wastes the most money. Teams pick a platform on a demo, then discover that 60% of their volume is a returns question the tool's scope excludes. Label first, buy second.
Tuning the SLA target instead of the workflow is the cheapest mistake and the easiest to keep making. A tighter target changes the number you report without changing what happens to a case. It works for exactly one quarter, then the queue grows back and the target gets quietly loosened.
The subtler one is treating escalation as failure. If your reporting punishes the team whenever a case reaches a person, agents will stretch the automated scope past what it can safely handle, and the damage shows up as a refund error or a public complaint rather than as a metric. Escalation is the safety valve that makes the rest of the system safe to run.
One more trap: letting the queue absorb the work because nobody owns the number. A first-response time with no named person responsible is a wish, not an operating target. Assign it to whoever touches routing, and give them the authority to change the routing rules.
When to Act
You should move on this when two conditions hold at once. Your monthly case volume is climbing with sales rather than sitting flat, and a large share of those cases are lookup-shaped. If both are true, the queue will keep costing you more each month you wait, and the fix gets easier while the volume is still small.
Hold off if your volume is genuinely low, under a few hundred cases a month. At that scale, a part-time person and better saved replies handle the load, and adding a system creates more upkeep than it removes. Hold off, too, if most of your tickets are judgment calls about unusual products or custom orders. Automation handles the routine, and a business with very little routine should not buy routine-handling software.
The ceiling matters as much as the floor. If you are processing thousands of cases a month across a wide product range, check whether the approach you are considering states a maximum volume, and take that number seriously. A tool that performs well at 800 cases can behave differently at 5,000.
The decision you are actually making is not whether to speed up your queue. It is whether to keep staffing a queue that exists mainly to route factual questions to people. That is a different business than the one you are running now, and it is cheaper.
How We Approach This
We built Loqum as a managed AI teammate for e-commerce support, and the design choices follow directly from the argument above. Our teammate works inside the helpdesk you already use as a normal user account, so there is no migration and no second platform for your team to check. Answers come from your approved policies, your customer orders, and your product catalogue rather than from general knowledge.
You can read every conversation as a ticket you can override. We are not a chatbot bolted onto a storefront: our teammates answer from approved sources and transfer to a human teammate the moment the case leaves their depth. Judgment stays with your people, and we say so plainly.
The part clients tend to underrate is that someone else runs it. Each teammate has an accountable Loqum AI Engineer who audits traffic and publishes a monthly report and capability plan, so the teammate improves without you becoming its maintainer. We build it, train it, and run it; you get the output instead of the upkeep.
Two honest limits. We accept a limited number of stores, and the roster can be full when you ask. We are also not positioned for stores handling more than 4,000 support cases per month. If your volume sits under that and your repeat tickets are lookup-shaped, start with the pricing page for the current tier, then book a call so we can look at your actual ticket mix before anyone commits.
Frequently Asked Questions
How can I improve customer response time?
Cut the number of tickets that require a human first reply. Label your last 30 days of cases as either data lookups or judgment calls, then find out which lookup categories repeat most. Order status, return questions, refund checks, and delivery changes can be answered from your order data without an agent in the loop. Every lookup you remove shortens your average response time without changing anyone's working hours. Once the lookup tickets are gone, your remaining queue is smaller and your agents reach the hard cases faster.
How to increase the response time?
If the goal is a longer response time rather than a shorter one, the practical method is to add work to the front of the queue: route every automated case back to a human for approval, require a manager sign-off before any refund reply, and stop letting the system close anything on its own. Make it deliberate and dated, though. Teams that leave approval gates in place permanently are choosing a slower queue by accident rather than on purpose.
What are 10 ways to improve customer service?
Ten tactics across the two levers: on the speed side, delete lookup tickets from the queue, define an escalation rule before automating anything, measure first-response time per category rather than overall, restrict tool access to read-only, and give one person ownership of the routing rules. On the quality side, keep humans on disputes and damaged goods, publish a monthly review of automated conversations, expand scope one category at a time, tell customers when a person is joining the thread, and audit satisfied customers' closed cases for near misses. Most of the value sits in the first five.
What is the 10 to 10 rule in customer service?
The 10 to 10 rule holds that a customer's first ten seconds and last ten seconds with your brand shape how they remember the whole interaction, so the greeting and the sign-off deserve the same attention as the resolution itself. It maps cleanly onto ticket response time: a fast first reply that reads as a generic acknowledgment fails the first ten seconds even though it hits the SLA. A teammate that answers a real question in the first message passes it. Speed that arrives as a form letter is not speed the customer counts.
If your queue is growing with your sales and the repeat tickets are factual rather than difficult, the fastest path to a better response time is deleting that work rather than staffing it. Look at your current pricing tier and book a call so we can check your ticket mix against what we handle.