Learn How to Improve E-commerce Customer Service by Fixing Routing
Learn how to improve e-commerce customer service by fixing routing, policy scope, and escalation rules, not by buying another platform.
Most attempts to improve e-commerce customer service fail because the store buys a new platform before it decides who answers what, in what order, and under which policy. The leverage lives in routing, policy scope, and escalation rules, and those are configuration decisions, not purchase decisions. You can swap helpdesks twice in a year and still watch your first-response time climb, because the tool never chose which questions were answerable in one message.
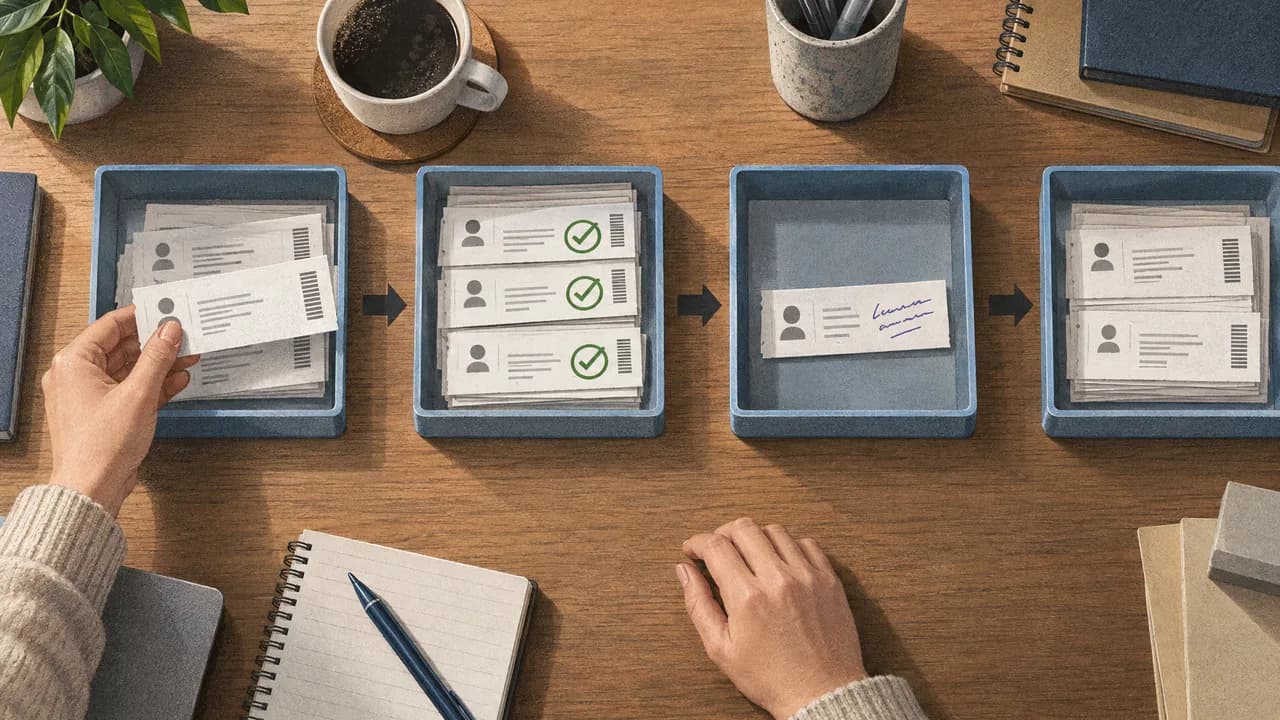
The hard part is that configuration work is invisible. It does not produce a launch email or a screenshot for a board deck. It produces a queue where a refund request with a photo attached never lands in the same bucket as a question about a tracking number, and where the person on shift knows exactly which twelve cases they own.
The Answer in One Paragraph
Improving e-commerce customer service starts with measurement and policy scope: find the five to ten question types that generate most of your contacts, decide which are answerable from approved sources in one reply, and route everything else to a named human owner. Only after that do you evaluate tools.
That number does not describe an e-commerce shopper, and it is still the useful benchmark here, because a service-expectation survey taken in a different sector tells you what "timely" means to a person who just pressed send on a form. A day is the ceiling. Most buyers treat a few hours as the norm.
Which is why "our replies are thoughtful" is not a defense. A thoughtful reply that arrives on Thursday for a question asked on Tuesday has already lost the customer, and the cost shows up later as a chargeback or a one-star review about shipping.
What Support Configuration Actually Means
Support configuration is the set of decisions that determine what happens to a message after it arrives: which queue it enters, which policy governs it, who owns it, and when it stops being that person's problem. It is distinct from tooling, which is only the surface those decisions run on.
Three groups of people are served by getting this right, and they want different things. The buyer wants one reply that resolves the issue. The founder wants support cost to grow slower than order volume. The agent wants to stop re-reading the same twenty messages about a delayed courier.
That is why the work is not "improving customer service" in the abstract. It is narrowing the definition of a support case until the definition matches what your team can actually resolve from a screen. Early e-commerce support research pursued a similar aim: SuperAgent: A Customer Service Chatbot for E-commerce Websites (2017) framed the problem as answering from a product catalogue and order data rather than open-ended conversation. That framing holds up. The scope is the product.
The adjacent concepts matter too, because they get conflated. Response-time management is one lever. Case deflection is a different one, and it usually moves the metric that matters least. What most owners call "bad support" is actually an undefined case scope, where every message could be anything and so every message gets handled slowly.
How Routing and Escalation Work in Practice
Start with what arrives. A queue is not a list of problems; it is a list of intents wearing problem costumes. A message reading "where is my order, this is the second time I've asked" is two distinct records: a shipment status lookup and a relationship repair, and they belong to different people.
Routing decides the first of those. When an order number is present and the shipment is in transit with a known scan date, the answer is a data lookup, and a data lookup does not need judgment. When the order number is present but the shipment has not moved in six days, the answer requires a decision about what you are willing to promise, and that decision should not be invented on the fly by whoever opens the ticket first.
Escalation decides the second. A working escalation rule names a condition and a person, not a sentiment. "Angry customer" is not a condition. "Second contact on the same order within seventy-two hours" is, and it fires the same way at 2am as it does at noon.
Here is the part most stores skip. Policies have to be written down before routing can be automated, because routing without policy just moves the ambiguity. If your return window differs by product category, that difference needs to exist in a document someone can point at, or every agent will interpret it slightly differently and your customers will compare notes.
The mechanism behind all of this is unglamorous. You are reducing the number of decisions a human has to make per ticket, and pushing the residual decisions to the person who is actually accountable for them.
The Order to Fix Things In
The sequence matters more than the speed. Each step produces the input the next one needs, which is why skipping ahead is how stores end up with an expensive tool and an unchanged queue.
- Pull the last ninety days of tickets and tag each one by intent, not by department. You are looking for the ten intent labels that cover the largest share of volume.
- Write the policy that governs each of those ten. If a policy does not exist, that is your finding, and it outranks everything else on this list.
- Define the resolution an agent can complete from approved sources alone, in one reply, without checking with anyone.
- Set the escalation trigger for each intent that fails that test, with a named owner and a response expectation.
- Measure first-response time and repeat-contact rate by intent, and treat a rising repeat-contact rate as a policy problem rather than an agent problem.
- Only now evaluate whether a platform, a hiring plan, or a managed service is what removes the remaining constraint.
Steps one through five cost time and no money. Step six is where the budget conversation belongs, and it belongs there because by that point you know which intents are volume drivers and which are genuinely hard.
There is a second reason to work in this order: it survives a tool migration. Intent labels and policy documents are portable. Ticket tags that existed only inside one helpdesk's custom fields are not, and rebuilding them after a switch is how a "quick platform move" becomes a quarter-long project.
What to Look For
When you do get to step six, evaluate options on dimensions rather than on demos. Every vendor demo looks fast, because the demo queue has twelve tickets in it and none of them are ambiguous.
| Dimension | What to check |
|---|---|
| Case scope | Which intents can it resolve end to end, and what does it do with the rest? |
| Source of truth | Does it answer from your written policies and order data, or generate plausible text? |
| Transparency | Can you read every conversation as an ordinary ticket and override it? |
| Escalation | Where does it stop and hand over, and is that boundary documented? |
| Ownership | Who is accountable when its answers drift from your policy? |
| Cost shape | Fixed, per case, or per seat, and how does it behave when volume doubles in November? |
| Ceiling | At what monthly case volume does it stop being the right fit? |
Two dimensions deserve more attention than they usually get. Source of truth separates a system that quotes your return policy from one that invents a return policy, and the difference only shows up on the cases you would least like to be wrong about. Cost shape decides what peak season does to your margin. A per-seat model charges you for a spike you can predict; a fixed model does not, which is a trade-off rather than a win, since fixed pricing usually comes with a volume ceiling.
If your constraint is genuinely ticket handling rather than tooling, handling more support tickets without breaking margin works through the arithmetic of that decision.
Where Stores Get This Wrong
The most expensive mistake is hiring before scoping. Adding a second agent to a queue with undefined intent boundaries doubles your capacity to handle ambiguous cases slowly, and it doubles your payroll at the same time. The queue looks better for about six weeks. Then volume catches up and you are back where you started with one more salary in the mix.
Less obvious is the deflection trap. A store builds a self-service page, watches deflection climb, and concludes support improved. What often happened is that the easy questions stopped arriving and the hard ones still did, so the average handling time per remaining ticket went up while the headline number moved in a flattering direction. Deflection is not a service metric. Repeat-contact rate is, because it measures whether your first answer actually held.
Then there is the policy gap that everyone knows about and nobody fixes. Somewhere in your store there is a question with two answers, and the answer depends on which agent opens the ticket. Furniture delivered to a third-floor walkup, a discount code applied after a price change, a return on a final-sale item that arrived damaged. These are not edge cases; they are the cases that generate a second and third contact, and they stay expensive until someone writes the sentence that settles them.
A fourth pattern is subtler and harder to catch: measuring the queue rather than the customer. Teams track daily ticket counts and celebrate a quiet Tuesday without asking whether the quiet came from fewer problems or from more people giving up. A support operation that resolves fewer contacts but resolves them completely is healthier than one that closes more tickets with a template.
When to Act, and When to Wait
You are ready to change something when three signals appear together. First-response time is drifting up over consecutive weeks, not spiking on one bad day. Repeat contacts are growing as a share of total volume, which means your first answers are not holding. And you can name the handful of intents driving most of the work, because if you cannot name them, you have a discovery problem before you have a support problem.
Wait if your volume is genuinely small and stable. A store handling a few hundred cases a month with a single owner and clear policies does not need a system; it needs the policies written down so the next hire inherits them. Buying tooling at that stage mostly buys you a migration.
The judgment call sits in the middle. If your intent map shows that most volume is answerable from order data and written policy, and your remaining cases genuinely need human judgment, then you are looking at a division of labor rather than a headcount decision. That is the moment to evaluate a managed teammate, a platform, or a hire, in that order of reversibility. A hire is the hardest to undo. A platform migration is slower than it looks. A configured service can be turned off.
Set the trigger date rather than waiting for the feeling. If your peak season starts in November, the configuration work needs to be finished before the queue doubles, not during it. Everything you decide in the calm weeks is a decision you will not have to make at 11pm in the busy ones.
How We Approach This
We built Loqum around the argument in this article, which is why our product is deliberately narrow. A teammate sits inside the helpdesk you already use, as a user rather than a new platform to learn, so your existing routing and your existing ticket history stay where they are. It answers from your approved policies, order data, and product catalogue, and transfers anything outside that scope to a human teammate.
The configuration is the product. We write the case scope with you, restrict the tools to read-only access, and keep every conversation visible as an ordinary ticket you can read and override. Each teammate has a named Loqum AI Engineer who audits it monthly and reports on what it handled, what it escalated, and what it should learn next. You get the output rather than the upkeep.
We are also clear about where we stop. Judgment stays with your human agents, and the teammate escalates when it is out of its depth rather than guessing. We are not positioned for stores handling more than roughly 4,000 cases a month, we accept a limited number of stores and may be full, and capability expands gradually starting from simple tickets. If you want to see how the cost math works against hiring, what AI support actually costs per ticket lays out the comparison. If that fits your situation, the next step is a conversation about your intent map, not a demo.
Frequently Asked Questions
What are the 5 C's of e-commerce?
The five C's are typically given as customer, convenience, cost, communication, and consistency. Two of them are configuration problems rather than service attitudes. Communication breaks when a store has no written policy on what it will promise and when, and consistency breaks when the same question gets two different answers depending on which agent opens it. Convenience and cost are structural. Fixing the C's in practice means writing the policies and routing rules that make the answers repeatable, not training people to be friendlier.
What are the 7 C's of e-commerce?
The seven C's usually extend the five with competition and community, or with content and conversion depending on the source. The list varies because different frameworks stretch the same idea. What does not vary is that the operational C's carry the weight. A store that communicates consistently and answers predictably will outperform one that has thought carefully about community but cannot tell a customer whether a final-sale return is eligible without escalating the question. Treat any C-list as a checklist of decisions to write down.
What are 10 ways to improve customer service?
Ten real levers, drawn from the work above: tag ninety days of tickets by intent; write the policy behind each top intent; define what resolves in one reply from approved sources; name an escalation owner per intent; measure first-response time and repeat-contact rate; kill the deflection metric; keep every automated conversation readable and overrideable; give one person accountability for the system; test on your own historical tickets before committing; and re-check the routing when volume changes. Most of these cost time rather than money.
What is customer service in e-commerce?
It is the resolution of everything that happens between an order and a satisfied customer: order status, delivery changes, returns, refunds, product questions, and the relationship repair that follows a problem. In an online store it is largely asynchronous, which changes the economics. Each contact has a written record, so a vague answer is permanently visible, and each unresolved contact tends to generate another. That is why scope and routing matter more here than in a walk-in setting. The channel rewards precision.
If your intent map shows most of your volume is answerable from order data and written policy, the useful next step is a conversation about scope rather than a demo. Write to mailto:anna@loqum.io or book a call, and we will tell you honestly whether a managed teammate fits your volume or whether your money is better spent having someone write the policies first.