Check If AI Support Can Reduce Support Workload Before You Buy Anything
Check if AI support can reduce support workload in your store by measuring the routine share of your queue, not the demo that impressed you.
The honest test of whether AI support can reduce your support workload is not a vendor demo, it is the routine share of your own queue: roughly how many of last week's tickets were mechanical requests with one correct answer already sitting in your helpdesk, because that fraction is the part a scoped AI teammate can actually take off your plate.
Most teams skip that measurement and buy on the strength of a slick sandbox conversation. Then real tickets arrive, the AI guesses at a return exception it was never allowed to touch, an agent has to read and correct the reply, and the workload went sideways instead of down. That failure is not a model problem. It is a scoping problem, and it is measurable before you spend anything.
The One Number That Decides This
Open your helpdesk and export last week's tickets. Sort them into two piles. The first pile is everything with one correct answer that already exists somewhere in your systems: where an order is, whether a return window is still open, how to change a delivery address, which discount code applies. The second pile is everything else, the angry customer, the damaged item with photos attached, the wholesale request, the dispute you have to think about.
Your routine share is the size of the first pile divided by everything. Stores running a standard catalogue with mostly in-stock products tend to find between a quarter and a half of their queue in that first pile. Stores with heavy preorder, made-to-order, or custom work find much less.
That single percentage predicts the outcome better than volume, revenue, or which platform you sell on. A store with 400 tickets a month and a 45% routine share has more to gain than a store with 2,000 tickets and a 12% routine share, because the second store's queue is mostly judgment, and judgment is the one thing you should not hand over.
The metric vendors quote instead, "automation rate", is a different animal entirely. It counts how often the tool produced some reply, not how often a customer was satisfied and an agent was spared. The gap between those two numbers is where most disappointing rollouts live.
What Reduce Support Workload With AI for Ecommerce Actually Means
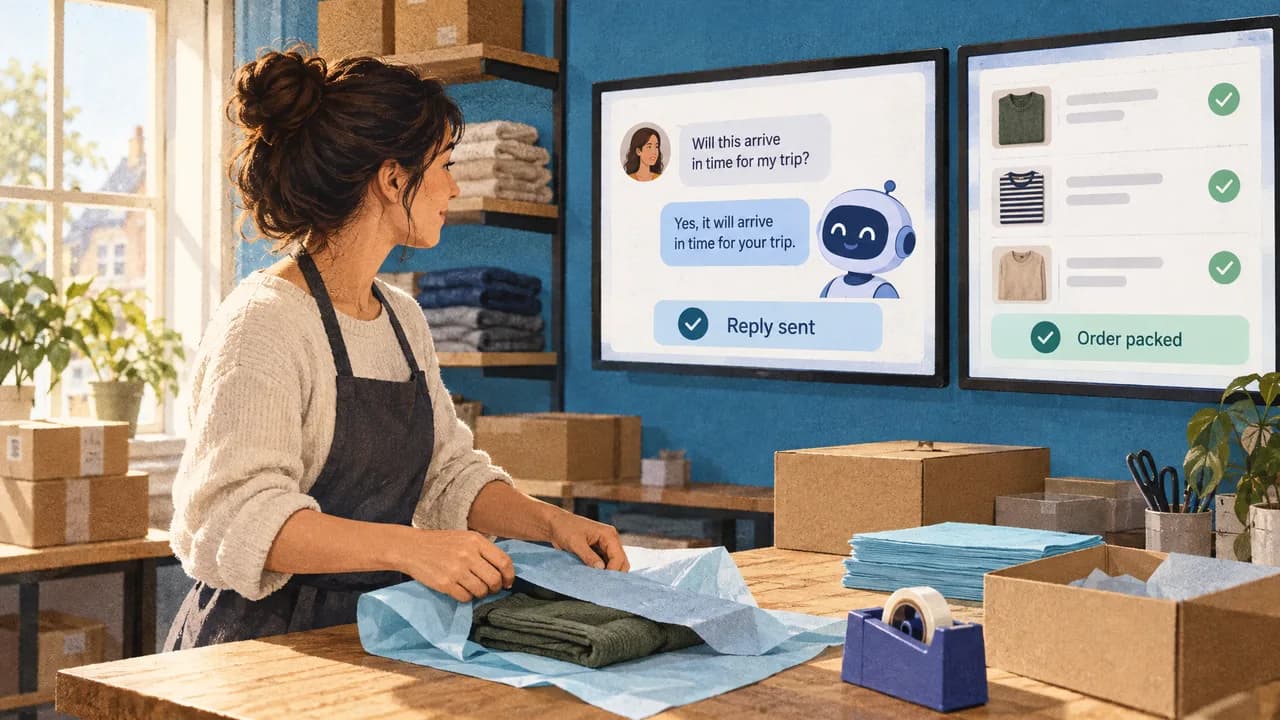
Reducing support workload with AI means removing named categories of tickets from human handling entirely, with an agreed escalation path for everything the AI cannot resolve, rather than speeding up an agent who still reads and sends every reply.
The distinction matters because a draft-and-approve tool feels like help and measures like more work. If an agent has to review every suggested reply before it goes out, you have added a step, not removed one, unless the drafted reply is right often enough that review takes seconds instead of minutes.
So the concept has three parts, and all three have to be true. A defined category gets handled without a human. The handling pulls from approved sources, so the answer is the one you would have given. And an escalation path exists for anything outside that category, with a person on the other end.
Adjacent ideas are easy to confuse with it. A macro library reduces typing but an agent still opens, reads, and sends every ticket. A self-serve help centre deflects some questions but only those customers willing to look for the answer. Proper workload reduction is the narrower thing: work that no longer reaches a person at all. If you want the margin side of the same argument, it is laid out in our piece on handling more support tickets without losing margin.
What to Look For Before You Switch Anything On
You are evaluating a decision, not a feature set. Six dimensions decide whether a tool removes work or relocates it, and you can score any option against them.
| Dimension | What good looks like |
|---|---|
| Scope definition | The tool states what it handles and what it refuses, in your terms, before you buy |
| Escalation path | Anything outside scope reaches a human with context attached, not a dead end |
| Answer sourcing | Replies come from your policies, order data, and catalogue, not the model's general knowledge |
| Auditability | Every automated conversation is readable and correctable in your helpdesk, as a normal ticket |
| Access limits | The tool reads what it needs and cannot change orders, issue refunds, or touch customer records beyond its brief |
| Cost shape | A per-case or per-ticket model you can reconcile against your queue, not a seat licence you grow into |
Write your own column beside that table and put a number on how many of last week's tickets each option would have touched. Vendors will describe capability in the abstract. Your queue is specific, and the only credible answer comes from your ticket export.
The access limit row deserves a second look, because it is where most comparisons are won and lost. A tool with broad write access is a liability you cannot audit at speed. A tool that only reads can still answer a large share of routine tickets, because most routine tickets ask for information rather than a change.
How to Run the Test on Your Own Queue
Do this before you take a second demo. It takes a couple of hours and it changes what you ask the next vendor.
- Export the last four weeks of tickets as a spreadsheet, with subject, first message, and resolution note.
- Tag each one as routine or judgment. Routine means one correct answer exists in your systems. Judgment means a person had to weigh something.
- Count the tags to get your routine share. Anything under about 20% means workload reduction from scoped automation will be modest, and you should hear that before you sign.
- Take twenty routine tickets and write down where the answer lives, whether that is the order record, a policy page, or a shipping partner's tracking. If the answer exists nowhere, an AI teammate cannot invent it, and that category belongs in the judgment pile.
- List the categories you would hand over first, starting with order status, then returns eligibility, then delivery changes. They are the easiest to source and the easiest to verify.
- Ask each vendor how their tool sources answers for exactly those categories, and what happens when a case falls outside.
Step 4 is the one people skip and regret. A tool can only answer from data you already hold in a readable place. If half your return rules live in one person's memory, no amount of training will fix that, and the fix is a policy document, not a purchase.
Once you have the routine share and the category list, the buying conversation flips. You are no longer asking what the tool can do in general. You are asking what it can do with your order status, your return window, and your shipping data, and you can check the answer against tickets you already have.
How Each Option Works Under the Hood
Four mechanisms get sold under the name AI support, and they move work in different directions.
Draft-and-suggest tools sit inside the agent's reply box and generate a candidate response. Nothing sends without a human. Workload moves down because typing and lookup speed up, and it never falls to zero, because every ticket still costs a read and a click.
Self-serve chatbots handle the customer before a ticket is created, working from a knowledge base. When the knowledge base is good and the customer is patient, the ticket never exists. When it is thin, the customer loops, gives up, and opens a ticket angrier than they started.
Scripted workflows run fixed logic: if the order is unfulfilled, send the tracking update. They are reliable inside their narrow corridor and brittle at the edges, which is fine if your edges are rare.
Scoped AI teammates answer free-form messages from a bounded set of sources, then escalate anything outside that set. The moving parts are a case scope, a set of readable data sources, and a handoff rule. Because the scope is bounded, an agent can trust the output in the categories it owns.
The workload difference comes down to where the human sits in the chain. Before the reply, as with drafts, the human is still the bottleneck. After the answer, as a reviewer of escalations, the human only handles what genuinely needed them.
Where Stores Get This Wrong
The mistake that costs the most is buying on the demo's automation rate. A sandbox conversation is curated by whoever built the demo, so it showcases the tool's strongest categories and hides the ones you care about. Ask instead for a written list of the categories the tool refuses, and check whether your biggest pain point is on it.
A subtler error is handing over tickets that need judgment because an agent is drowning. During peak season the temptation is real. But an AI teammate answering a dispute or a damaged-goods claim will produce a confident reply that is subtly wrong, and the customer will escalate anyway, now with a worse impression and more context for a human to read. Judgment stays with people, and the escalation rule exists precisely so that it does.
Then there is the store that measures success by deflection and celebrates a chatbot containing a frustrated customer for six turns. That customer's eventual ticket is longer and angrier than the original would have been. Deflection without resolution is not workload reduction, it is deferral with interest.
A quieter failure comes from skipping the data audit. Teams buy the tool, then discover their return policy lives across two documents and an email thread, their order data is behind a login the tool cannot read, and their product catalogue has no structured attributes. The tool works as designed and answers nothing useful, and the fix takes longer than the purchase did.
And the volume mismatch cuts both ways. Stores handling more than a few thousand cases a month have routing, workforce, and quality systems that a small scoped deployment will not plug into cleanly. We say plainly that we are not positioned for stores handling more than 4,000 support cases per month, and you should hear the same limit from anyone you evaluate.
How We Approach This at Loqum
Two design choices follow from the workload argument above. The teammate works from restricted case scope with read-only, least-privilege tools, and it is trained on your policies, customer orders, and product catalogue, so its answers trace back to something you approved. Every conversation is a normal, readable, overrideable ticket in your helpdesk, which means your agents can see what it did and correct it rather than trusting a black box.
The upkeep is ours, not yours. Each teammate has a named Loqum AI Engineer who runs a monthly audit, report, and capability plan, so the scope starts narrow and expands as the teammate earns it. Pricing is fixed monthly and case-based, with no claim of unlimited scale. If you want the arithmetic behind per-case pricing, we published our breakdown of what AI support actually costs per ticket.
Being honest about the edges is part of the proposition. Judgment stays with your human agents, the teammate escalates when it is out of its depth, and we accept a limited number of stores, so we may be full. Stores handling more than 4,000 cases a month should look at heavier platforms built for that scale. If you are under that line and your routine share is real, the current pricing is on our pricing page, and the fastest next step is to bring us your category list.
Frequently Asked Questions
Which of the following can AI be used for to reduce teacher workload?
Grading essays and counselling students are not tasks a scoped support teammate handles, and this article does not pretend otherwise. The transferable version of that question is about categories with one correct answer and a readable source. Order status, returns eligibility, delivery changes, order edits, and discount codes fit that description in a store's queue. Lesson planning and pastoral judgment do not, which is exactly why the escalation rule matters more than the automation rate. A tool that attempts everything will hand back corrected work; a tool scoped to routine requests removes it.
What are some examples of AI workloads?
In a support queue, the workloads divide cleanly. Retrieval workloads pull a fact the customer asked for: where the order is, whether the return window is open, what the delivery date is. Transactional workloads make a small, defined change: an address edit, a discount code applied, an order cancelled inside the allowed window. Classification workloads sort what arrives and route it, which is the part that decides whether a person ever opens the ticket. Judgment workloads, disputes, exceptions, and upset customers, are not AI workloads in this model. They belong to agents, with the AI handing over context.
How long before I know whether it is working?
Give it one full cycle, not one week. The routine share you measured before launch tells you what the ceiling looks like, and the first month tells you whether the teammate is reaching it inside the categories you handed over. Track two things: how many tickets were resolved without an agent touching them, and how many escalations arrived with enough context that the agent did not have to reread the whole thread. If the second number is good and the first is low, widen the category list. If escalations keep arriving wrong, the scope is too wide and should be pulled back.